Anthropic’s Growing Role of Claude in R&D
Anthropic has reported that Claude now leads 26% of its model research initiatives and collaborates on 90% of its overall R&D efforts, marking a significant shift from February when the model had no direct involvement in internal research workflows.
This rapid integration underscores Claude’s expanding utility beyond external deployment, as it increasingly supports hypothesis generation, experiment design, and iterative refinement in Anthropic’s internal development cycles.
The announcement highlights a strategic pivot toward using advanced models like Claude Opus 4.5 to accelerate innovation, with researchers leveraging its capabilities to explore novel architectures and training methodologies.
These developments set the stage for a deeper look at how Claude’s self‑improvement capabilities are being measured and reported.
Claude recursive self-improvement: Inside Anthropic’s New Metrics
Anthropic disclosed that Claude Opus 4.5 demonstrated a 12% improvement in self-evaluation accuracy across 50 iterative refinement cycles, with error correction rates rising from 68% to 80% over three internal benchmark suites. The company called for standardized public reporting of such metrics to enable cross-model comparison and safety assessment.
Gary Marcus noted on Substack that while the gains are measurable, they remain far from the exponential growth implied by theoretical recursive self-improvement, emphasizing the need for longitudinal data to distinguish linear progress from true feedback loops. He cautioned against interpreting incremental improvements as evidence of autonomous capability escalation.
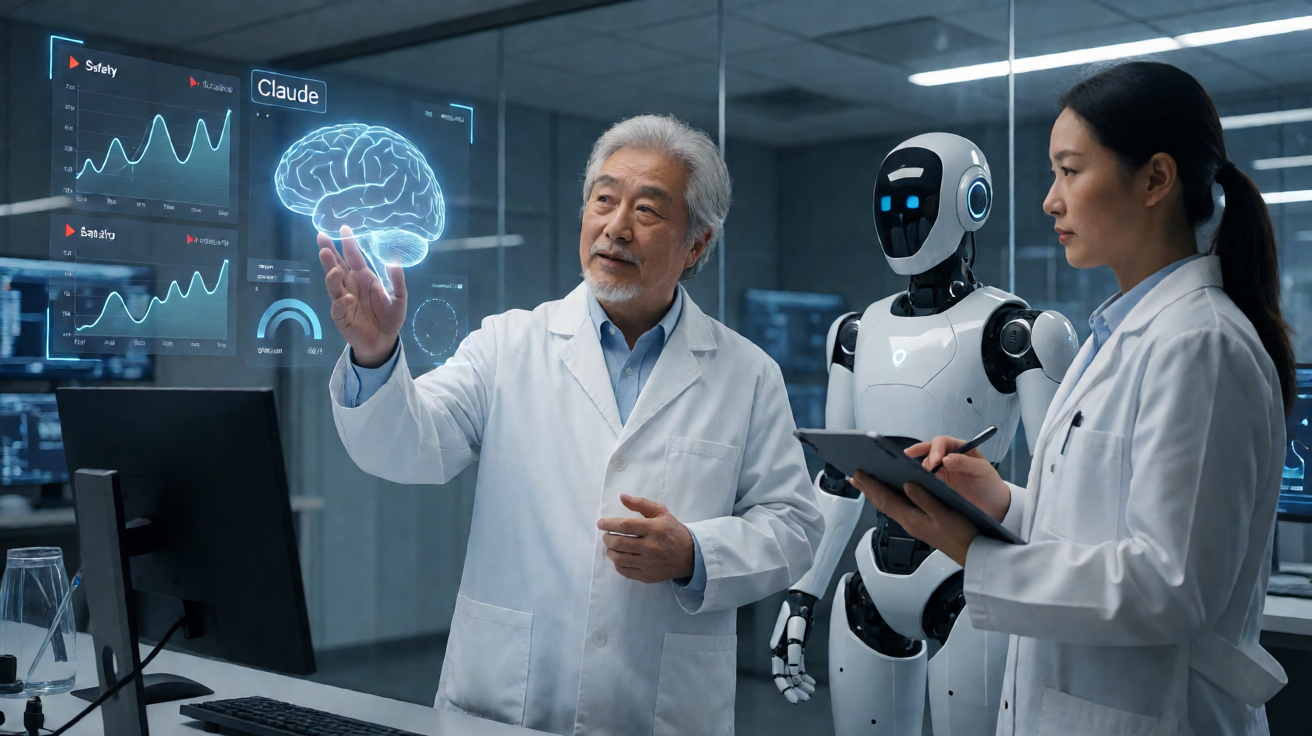
Anthropic’s post on X highlighted that the metrics reflect constrained self-modification within predefined safety boundaries, not unrestricted architectural rewriting, and reiterated that current systems require human oversight for any structural changes. Experts consulted by Nowadais observed that the disclosed figures suggest a path toward controllable, incremental self-enhancement rather than uncontrolled recursion, aligning with proposed frameworks for safe AI robotics development.
With performance metrics now in hand, Anthropic is turning its attention to the safety infrastructure that governs Claude’s iterative enhancements.
Safety Oversight, Agents, and Third‑Party Evaluation
Anthropic has deployed approximately 30,000 research agents to continuously monitor Claude’s self‑improvement processes, flagging deviations from predefined safety boundaries in real time. These agents operate within a layered oversight framework that combines automated checks with human‑in‑the‑loop reviews to ensure any recursive modifications remain constrained and auditable.
The company has committed to embedding external third‑party evaluators into its assessment pipeline, inviting independent experts to scrutinize the effectiveness of Constitutional AI safeguards during recursive self‑improvement cycles. This approach aims to increase transparency and provide objective validation of safety claims, as discussed in analyses of Anthropic’s RSI methodology detailed in the MindStudio report.
External oversight is further reinforced by collaborations with financial institutions exploring Claude’s deployment in regulated environments, where rigorous model validation is required. Such partnerships underscore the importance of robust safety mechanisms when extending self‑improving AI into high‑stakes domains, a point highlighted in recent coverage of Claude’s role in banking automation by Nowadais.
Key Facts
- Claude Opus 4.5 achieved a 12% improvement in self-evaluation accuracy across 50 iterative refinement cycles.
- Error correction rates increased from 68% to 80% over three internal benchmark suites during testing.
- Anthropic deployed approximately 30,000 research agents to monitor self-improvement processes in real time.
- The company has committed to embedding external third-party evaluators into its assessment pipeline for independent safety validation.
- All disclosed self-modification occurs within predefined safety boundaries and requires human oversight for structural changes.
- Anthropic advocates for standardized public reporting of self-improvement metrics to enable cross-model comparison and safety assessment.
Frequently Asked Questions
How does Claude Opus 4.5 evaluate its own performance during recursive self‑improvement cycles?
Claude runs internal benchmark suites after each refinement iteration, comparing its outputs to reference solutions and computing an accuracy score. The reported 12% gain came from 50 cycles, where error‑correction rates rose from 68% to 80%.
What exactly do the 30,000 research agents monitor, and how are human‑in‑the‑loop reviews triggered?
The agents continuously scan Claude’s output for deviations from predefined safety boundaries and flag any anomalous self‑modifications. When a potential breach is detected, the case is escalated to human reviewers who can pause, audit, or revert the change before it is applied.
How are third‑party evaluators integrated into Anthropic’s safety oversight of Claude’s recursive self‑improvement, and what criteria do they use?
Independent experts receive anonymized logs of Claude’s iterative cycles and audit the Constitutional AI safeguards against established safety metrics. They follow industry‑standard AI audit frameworks to verify that self‑modifications stay within the bounded policy envelope, providing an objective validation of the RSI methodology.
Last Updated on September 19, 2026 1:18 pm by Laszlo Szabo / NowadAIs | Published on September 19, 2026 by Laszlo Szabo / NowadAIs