Nemotron 3.5 Super VL: A Multimodal Model for Enterprise Agents
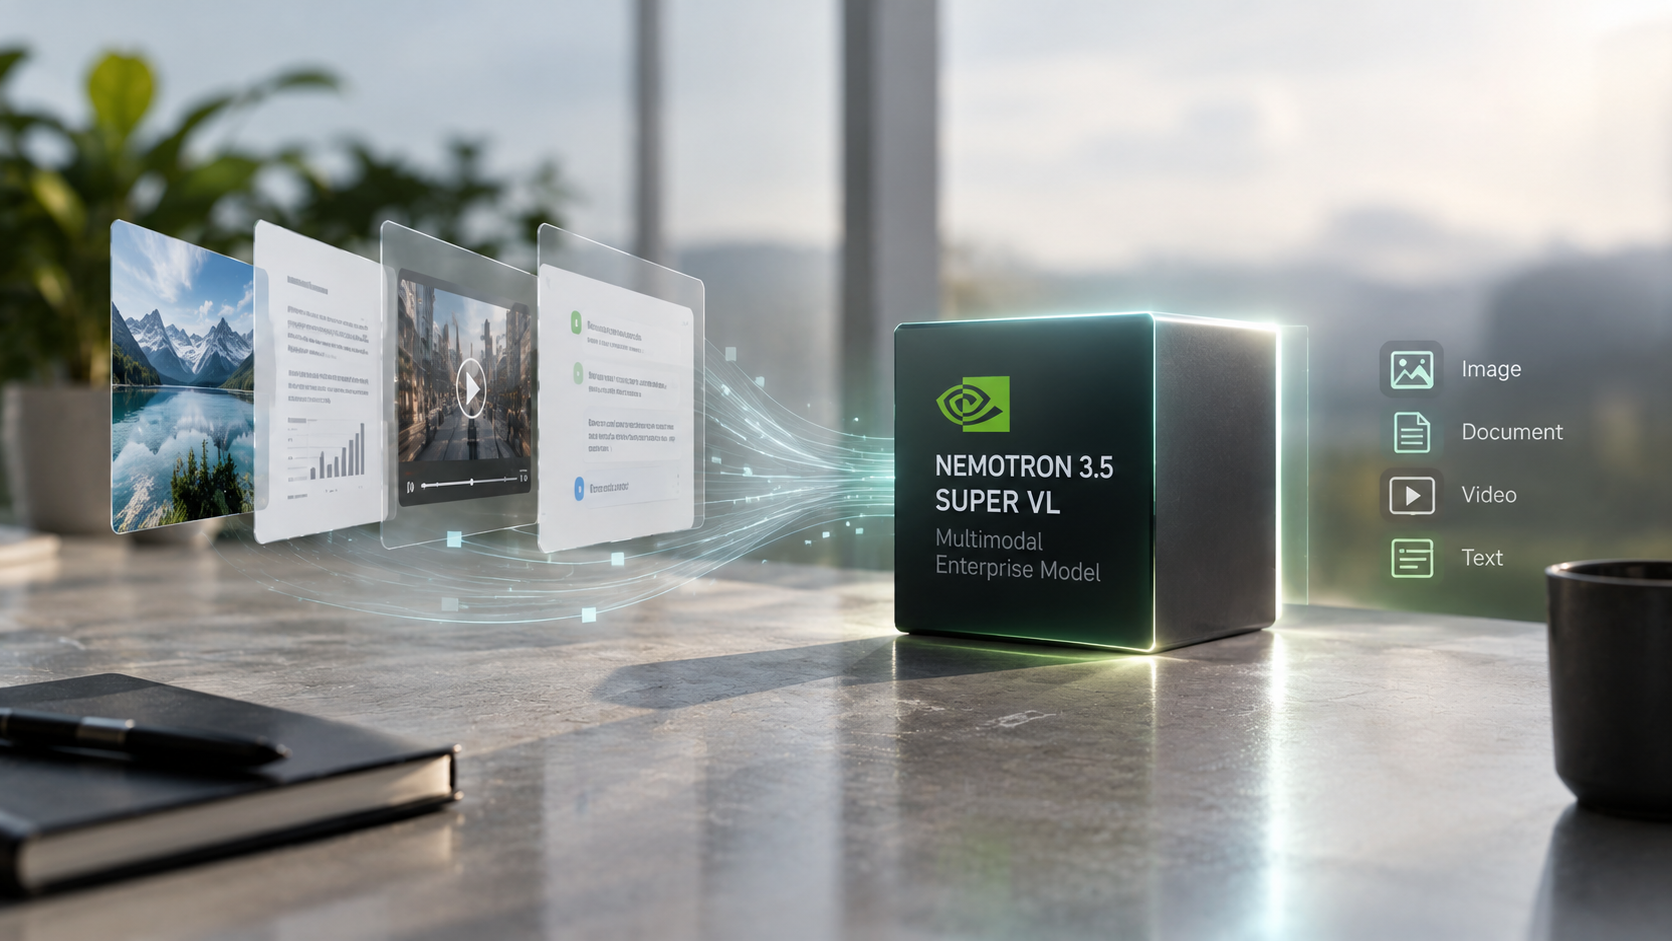
Nemotron 3.5 Super VL is an open, customizable multimodal model built for specialized enterprise workflows. The model uses a 120-billion-parameter mixture-of-experts architecture with 12 billion active parameters per token, enabling efficient inference while maintaining broad reasoning capacity.
It provides unified understanding across text, image, document, and video inputs, allowing enterprise agents to process diverse data types within a single system. Developers can fine-tune and deploy the model for domain-specific tasks without relying on closed-source alternatives.
NVIDIA details the model’s capabilities and deployment options in their official announcement. For background on how large language models process and generate tokens, see this explainer on LLM architecture.
These capabilities are already being put to work in real‑world enterprise deployments, as described below.
Real-World Deployments: Scale AI, Ramp, and Beyond
Organizations including Scale AI and Ramp are post-training Nemotron 3.5 Super VL using NVIDIA NeMo to optimize the model for specialized enterprise tasks. Scale AI leverages the model for vendor credit processing, while Ramp applies it to receipt image extraction, adapting the base architecture to domain-specific document workflows.
These deployments report measurable gains in cost efficiency, reduced latency, and higher throughput compared to general-purpose alternatives. By fine-tuning the multimodal model on proprietary data, teams can automate document-heavy processes without relying on closed-source APIs.
Deployment options and implementation details are available through NScale’s hosting platform. For related coverage of NVIDIA’s broader enterprise AI initiatives, see reporting on NVIDIA Earth-2.
The practical impact of these deployments is reflected in the model’s performance metrics, which are summarized next.
Key Facts and Performance Highlights
- The model features a 120-billion-parameter mixture-of-experts architecture with 12 billion active parameters per token.
- Nemotron 3.5 Super VL delivers up to 3.5x higher throughput than comparable multimodal models, according to Artificial Analysis.
- It achieves strong results on multimodal benchmarks, including document understanding and visual question answering tasks.
- Quantized versions are available to reduce memory footprint and lower inference costs for enterprise deployments.
- The model supports unified processing of text, image, document, and video inputs within a single architecture.
- Open weights allow developers to fine-tune and customize the model for domain-specific workflows without closed-source dependencies.
Beyond raw performance, NVIDIA provides a suite of inference optimizations and flexible deployment paths to help enterprises adopt the model at scale.
Inference Optimizations and Deployment Paths
Nemotron 3.5 Super VL uses LiLiCorr speculative decoding and multi-token prediction to increase token generation speed while maintaining output quality. NVFP4 quantization reduces memory requirements, allowing larger context windows and lower inference costs on supported hardware.
Developers can deploy the model through NVIDIA NIM microservices and NVIDIA Dynamo, which streamline serving and scaling across cloud and on-premises infrastructure. These tools help enterprises integrate multimodal capabilities into existing applications without managing low-level inference stacks.
Frequently Asked Questions
How can I fine‑tune Nemotron 3.5 Super VL for a proprietary document‑processing workflow?
You can use NVIDIA NeMo to load the open weights, add a task‑specific head (e.g., OCR or receipt extraction), and train on your labeled document images and text. The mixture‑of‑experts architecture allows you to keep only 12 billion active parameters per token, reducing compute while preserving performance. After training, export the fine‑tuned checkpoint and serve it via NVIDIA NIM microservices for seamless integration.
What hardware and quantization settings are recommended to achieve low‑latency inference for Nemotron 3.5 Super VL in an enterprise deployment?
NVFP4 quantization is the primary method to shrink the model’s memory footprint, enabling larger context windows on a single GPU. For optimal latency, NVIDIA A100 or H100 GPUs with Tensor Core acceleration are recommended, paired with LiLiCorr speculative decoding to boost token generation speed. Deploying the model through NVIDIA Dynamo or NIM microservices further streamlines scaling across cloud or on‑prem environments.
How does Nemotron 3.5 Super VL’s throughput compare to other multimodal models, and what benchmarks support this claim?
Independent testing by Artificial Analysis shows Nemotron 3.5 Super VL delivers up to 3.5× higher throughput than comparable 120‑billion‑parameter multimodal models on standard document‑understanding and visual‑question‑answering benchmarks. The model’s mixture‑of‑experts design, combined with speculative decoding, reduces per‑token compute, translating to faster inference on the same hardware. These results are reflected in real‑world deployments at Scale AI and Ramp, where latency improvements and higher throughput were reported.
Last Updated on October 16, 2026 6:59 pm by Laszlo Szabo / NowadAIs | Published on October 16, 2026 by Laszlo Szabo / NowadAIs