Why Sovereign AI Matters for German Public Sector
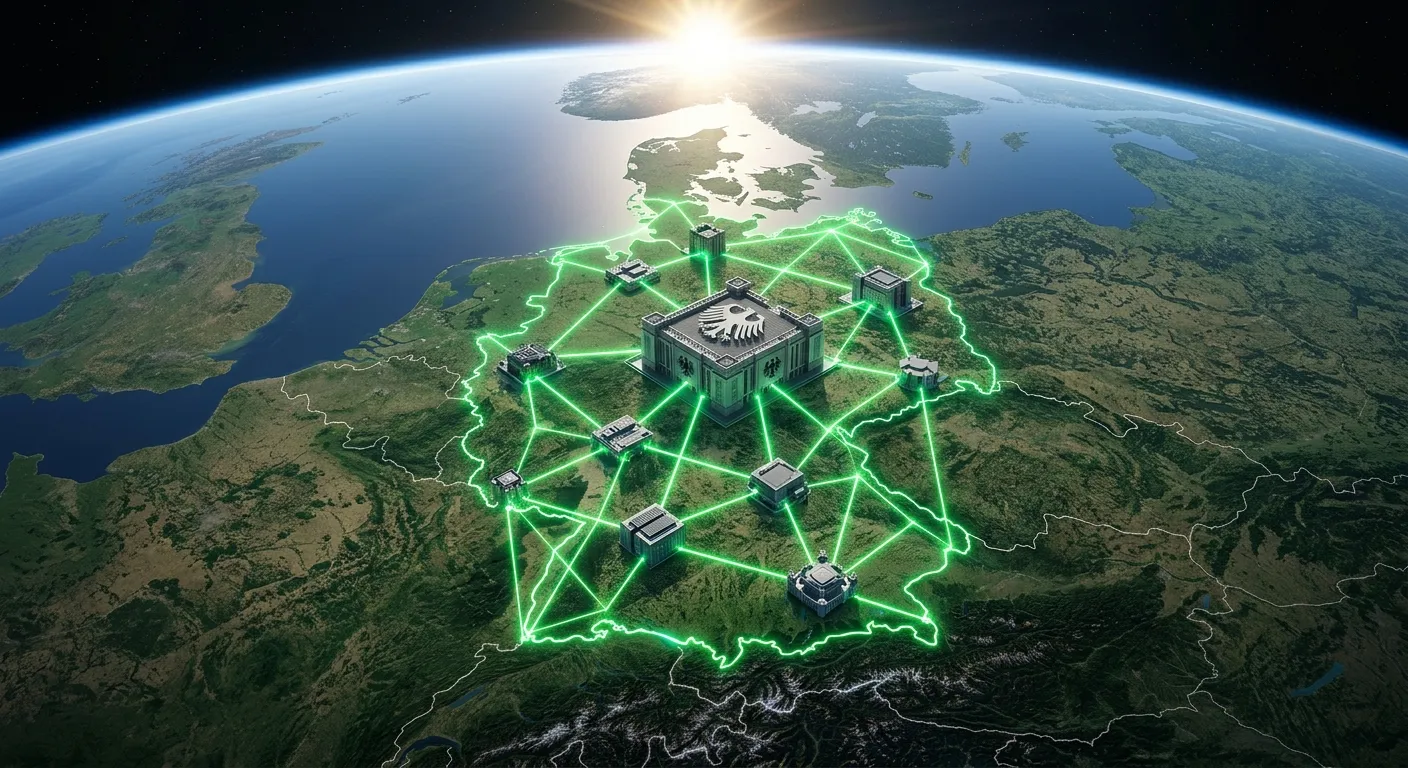
German public agencies operate under strict data‑protection rules, including the GDPR and sector‑specific regulations such as the BSI Grundschutz catalogues. These frameworks require that personal and classified data remain under national jurisdiction, limiting the use of models hosted on non‑EU infrastructure. As a result, ministries and municipal IT departments are actively searching for large language models that can be deployed on‑premises or within certified German cloud environments.
Aleph Alpha has positioned itself as a domestic alternative by offering the Kolibri language model family, which is trained and hosted in Germany and designed to meet BSI compliance requirements. The company emphasizes transparency through explainable AI features and contractual guarantees that data never leaves sovereign territory. For a deeper look at how these architectures function under the hood, see how large language models work.
These considerations highlight why a sovereign solution like Kolibri is especially relevant for German public‑sector deployments.
Kolibri language model: Technical Architecture and Sovereign Design
Kolibri employs a mixture‑of‑experts (MoE) architecture with 78 billion total parameters, of which only 3.5 billion are active during inference. This sparse activation pattern allows the model to run on a single GPU with 24 GB of VRAM while maintaining performance comparable to dense models of similar active size. The model supports a 32,768‑token context window and is released under the Apache 2.0 license, permitting unrestricted commercial use and on‑premises deployment.
Details on the training methodology, routing mechanism, and benchmark results are available in the official launch blog, a technical write‑up on Daily.dev, and the Hugging Face model card.
Understanding Kolibri’s design also requires placing it within the broader competitive landscape.
Competitive Landscape: IBM, Anthropic, and the European Sovereign AI Race
IBM is pursuing a similar sovereign strategy with its self‑hosted Bob AI platform, which targets regulated enterprises that require full infrastructure control and data residency guarantees. While Bob emphasizes integration with existing IBM hybrid‑cloud stacks and watsonx governance tooling, Kolibri differentiates itself through its open‑weight Apache 2.0 release and a sparse MoE architecture that reduces hardware requirements for on‑premise inference.
Anthropic’s Claude Opus 4.5 leads on raw benchmark performance and advanced reasoning capabilities, but it remains a closed, API‑first service with no native on‑premise deployment option. For German public‑sector buyers, that closed model creates a compliance gap that Kolibri is explicitly engineered to close, trading peak benchmark scores for auditability, data sovereignty, and the ability to run entirely within BSI‑certified environments.
Summarizing the most relevant details, the key facts are listed below.
Key Facts
- Launch date: 27 May 2025
- Sovereign design: trained and released by Aleph Alpha for German and EU regulatory compliance
- Model size: 78 billion total parameters, 3.5 billion active parameters via mixture-of-experts architecture
- Licensing: Apache 2.0, permitting unrestricted commercial use and on-premises deployment
- Target customers: German public sector, regulated enterprises, and organizations requiring BSI-certified environments
- Strategic significance: first open-weight sovereign LLM optimized for on-premise inference in European data-sovereignty contexts
Frequently Asked Questions
What hardware specifications are needed to run the Kolibri language model on‑premise in a German public‑sector environment?
Kolibri is designed to run on a single GPU with at least 24 GB of VRAM, thanks to its sparse mixture‑of‑experts architecture that activates only 3.5 billion of the 78 billion total parameters during inference. This allows organizations to deploy the model on standard server‑grade GPUs without requiring multi‑GPU clusters, while still supporting a 32,768‑token context window.
How does Kolibri’s mixture‑of‑experts (MoE) design impact inference latency compared to a dense model of similar active size?
Because only a subset of experts (3.5 billion parameters) are active per request, Kolibri processes inputs with fewer floating‑point operations, typically resulting in lower latency than a dense model that always evaluates all parameters. The routing step adds a small overhead, but overall the sparse activation yields faster response times on the same hardware.
What are the implications of Kolibri being released under the Apache 2.0 license versus IBM’s Bob AI licensing for on‑premise deployments?
The Apache 2.0 license permits unrestricted commercial use, modification, and redistribution of Kolibri’s code and weights, enabling organizations to tailor the model to their own compliance needs. In contrast, IBM’s Bob AI is a proprietary offering that requires licensing agreements with IBM and may restrict source‑code access, limiting customization and potentially adding additional costs for on‑premise use.
Last Updated on October 3, 2026 7:13 pm by Laszlo Szabo / NowadAIs | Published on October 3, 2026 by Laszlo Szabo / NowadAIs